The 2025 AI Agent Index: Accountability Infrastructure for Agentic AI Barely Exists
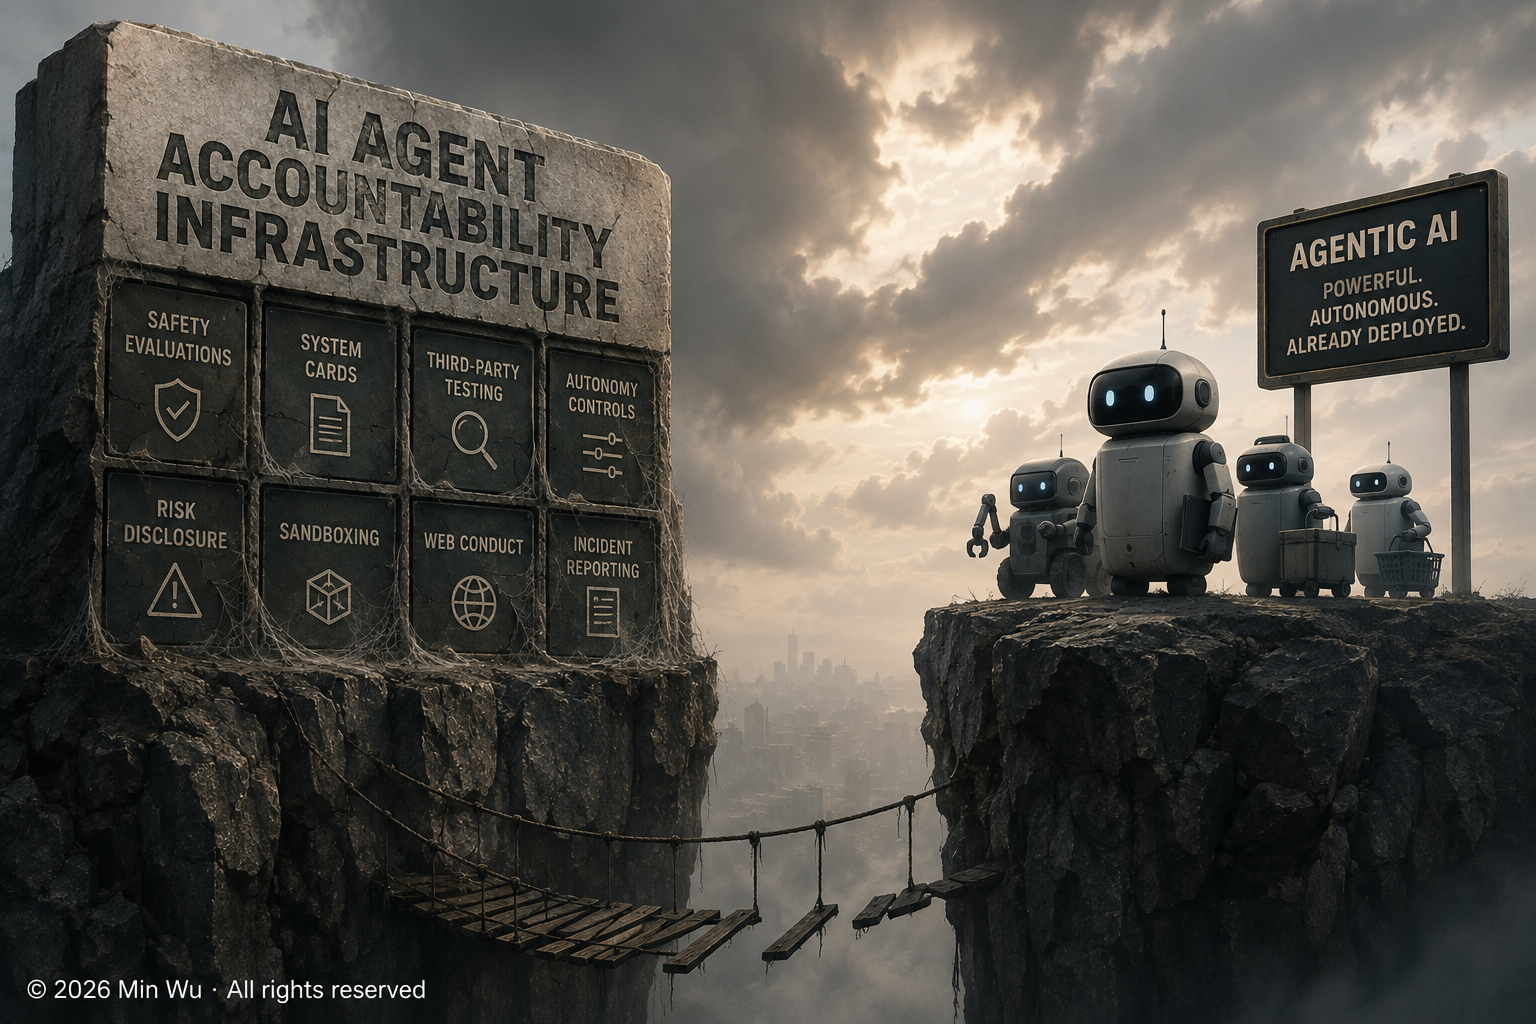
Of 240 safety-related fields across 30 deployed agents, 135 contain no public information — and of the 13 agents operating at frontier autonomy levels, only 4 disclose any agentic safety evaluations. Agentic AI governance has an observability problem before it even has an enforcement problem.
Agentic AI governance has had a measurement problem of its own.
For the past two years, researchers and governance teams have argued that accountability becomes harder when models acquire tools, memory, browsers, persistent execution, and authority to act. But there has been surprisingly little systematic evidence about what deployed agent developers actually disclose about those systems.
The 2025 AI Agent Index changes that.
Published at ACM FAccT 2026 by researchers from Cambridge, MIT, Stanford, Harvard Law, and Hebrew University, the Index examines 30 prominent deployed agents across their origins, capabilities, architecture, ecosystem, safety practices, and social impacts.
Instead of proposing another governance framework, it measures the current state of the ecosystem.
And the baseline is not encouraging.
📊 What the Numbers Actually Say
Across 240 safety-, evaluation-, and social-impact-related fields, 135 contain no publicly available information.
The gaps become even clearer at the system level:
- 25 of 30 agents disclose no internal safety evaluation results.
- 23 of 30 provide no information from third-party safety testing.
- Of 13 agents exhibiting frontier levels of autonomy, only 4 disclose agentic safety evaluations.
- Only 4 of 30 have agent-specific system cards.
Lead author Leon Staufer described the pattern as a “weaker form of safety washing”: developers tend to be substantially more forthcoming about what their agents can do than about evidence concerning their risks.
That distinction matters.
The problem is no longer simply that agentic AI might create an accountability gap. We now have a structured empirical baseline showing how much of the information required for accountability is simply unavailable.
Agentic AI governance has an observability problem before it even has an enforcement problem.
You cannot meaningfully govern risks that developers do not document.
🤖 Which Agent Categories Are Most Opaque
The Index also reveals a gradient by agent type:
| Agent Category | Safety-Related Fields Missing | Typical Autonomy |
|---|---|---|
| Enterprise agents | 66% (69/104) | Can reach Level 3–5 in deployment |
| Browser agents | 60% (24/40) | Typically Level 4–5 |
| Chat agents | 44% (42/96) | Generally lower autonomy |
The relationship is uncomfortable: the categories capable of taking more consequential actions also tend to provide less safety information.
Enterprise agents are particularly important.
A system may appear relatively constrained during design and testing but become substantially more autonomous once connected to production workflows, enterprise data, external tools, and delegated permissions. The Index notes that enterprise agents can move from relatively low autonomy during development toward Level 3–5 behavior in deployment.
The transparency problem extends beyond formal safety evaluations.
For agents interacting with the open web, 16 of 30 provide no clear statement about practices such as robots.txt compliance, CAPTCHA handling, or web-access methods.
These are not necessarily catastrophic safety failures. But they illustrate a more basic governance problem: in many cases, outsiders cannot reliably determine how the agent behaves operationally.
For conventional software, that would already be uncomfortable.
For software that acts autonomously, it becomes an accountability problem.
🌐 The Ecosystem Concentration Risk
Another finding deserves more attention: most agents ultimately depend on a remarkably small number of foundation-model providers.
Outside developers operating their own proprietary models — including major frontier labs and several Chinese developers — much of the agent ecosystem is built on models from a handful of providers such as OpenAI, Anthropic, and Google.
That creates concentration risk.
An agent may appear to be an independent product, but its behavior can depend on an upstream model provider whose pricing, availability, capability, safety mitigations, or model updates are outside the agent developer’s control.
The dependency chain increasingly looks like:
foundation model → agent framework → agent product → deployment environment
A significant change at one upstream layer can therefore propagate through many otherwise independent downstream systems.
But concentration cuts both ways.
The same architecture creates governance leverage. Safety improvements implemented at the foundation-model layer — stronger tool-use controls, better monitoring interfaces, improved model documentation, or more robust safeguards — can propagate across a large number of downstream agents.
The Index therefore exposes both a systemic vulnerability and a potential control point.
📏 The FMTI Parallel — and Where It Diverges
There is a useful precedent.
When Stanford’s Foundation Model Transparency Index launched in 2023, foundation-model developers disclosed remarkably little information, averaging roughly 37 out of 100 on its transparency indicators.
The FMTI created something that had previously been missing: a repeatable public benchmark against which developer disclosure could be compared.
Developers subsequently engaged with the Index and its researchers, although progress has hardly been monotonic. In the most recent edition, the mean transparency score actually fell 17 points year-over-year, against an updated and in some respects stricter indicator set.
The Agent Index resembles the early FMTI in one important respect:
it converts an abstract transparency complaint into a measurable baseline.
But agentic AI introduces a harder structural problem.
Foundation-model transparency can often be analyzed primarily at the developer and model level. Agentic systems distribute responsibility across multiple layers:
foundation-model provider → agent developer → orchestration/tool layer → deployer
Who is responsible when an agent behaves unsafely?
The model provider may argue that the downstream developer configured the system.
The agent developer may point to behavior inherited from the underlying model.
The enterprise deployer may rely on documentation supplied by both.
And the orchestration layer may introduce tools, memory, permissions, or execution logic that neither model-level nor application-level documentation fully captures.
That is accountability diffusion by architecture.
A regulator or risk team looking only at foundation-model documentation can therefore receive false assurance about a system whose real risk emerges from the agentic stack around the model.
⚖️ What This Means for Practitioners
The Agent Index provides the empirical baseline for a problem I previously described in Agentic AI and the Governance Gap.
That earlier argument was architectural: governance frameworks built around models struggle once AI systems begin acting through tools, workflows, memory, and delegated authority.
The Index now measures what that gap looks like in practice.
It also sharpens the issue raised in my GPT-5.6 Sol system card analysis. Even sophisticated frontier developers are still working through how to document the relationship between autonomy, capability, and control.
Against that backdrop, the fact that 26 of the 30 agents studied lack an agent-specific system card is more consequential than a simple documentation shortfall.
For developers, the Index points toward concrete missing infrastructure:
Agent-specific system cards. Agentic safety evaluations. Third-party testing. Sandboxing documentation. Web-conduct policies. Clear descriptions of autonomy and deployment controls.
For procurement, internal audit, AI governance, and model-risk teams, the Index is effectively a vendor due-diligence checklist in disguise.
Before asking whether an agent passed a safety evaluation, organizations may first need to ask whether such an evaluation exists — and whether its results are available at all.
🧩 Regulation Does Not Automatically Close the Gap
It is tempting to assume that emerging AI regulation will force this information into the open.
That is not guaranteed.
Requirements such as the EU AI Act’s Article 50 transparency obligations address important questions around AI interaction and synthetic content, but they do not amount to a general requirement for public agentic safety evaluations, agent-specific system cards, or detailed disclosure of autonomy controls.
Likewise, emerging audit requirements in specific jurisdictions and use cases can increase accountability without necessarily addressing the full disclosure gap measured by the Agent Index.
This distinction matters.
Transparency regulation is not automatically agentic safety transparency.
The Index is measuring information that many existing regulatory frameworks were not specifically designed to require.
That leaves an uncomfortable possibility: agent deployment could scale faster than the accountability infrastructure needed to observe it.
🔍 The Governance Gap Is Now Measurable
The most important contribution of the 2025 AI Agent Index may not be any individual statistic.
It is the creation of a baseline.
Before the Index, we could argue that agentic systems created accountability diffusion, weak documentation, and unclear responsibility.
Now we can measure part of it.
135 of 240 fields blank.
25 of 30 without disclosed internal safety results.
23 of 30 without disclosed third-party testing.
Only 4 of 13 frontier-autonomy agents disclosing agentic safety evaluations.
Those numbers can now move.
That is what made transparency indexes such as the FMTI useful: once disclosure becomes measurable, the next edition can tell us whether the ecosystem is improving or merely producing more capable systems around the same governance vacuum.
My read: The Agent Index establishes the missing empirical baseline for agentic AI accountability. The immediate problem is not simply that regulators lack rules for autonomous systems. It is that developers, deployers, auditors, and regulators often lack the information required to determine how those systems are being controlled in the first place.
What to watch: Whether publication at FAccT and increased scrutiny of agentic AI produce a measurable change in the next Index — particularly whether developers begin publishing agent-specific system cards, third-party evaluations, and clearer evidence about autonomy controls.
If they do, the Index will have become more than a measurement tool.
If they do not, it will document something equally important: the growing distance between agentic capability and the accountability infrastructure surrounding it.