The Token Transparency Gap: Why Agentic AI Still Hides Where Computation Goes
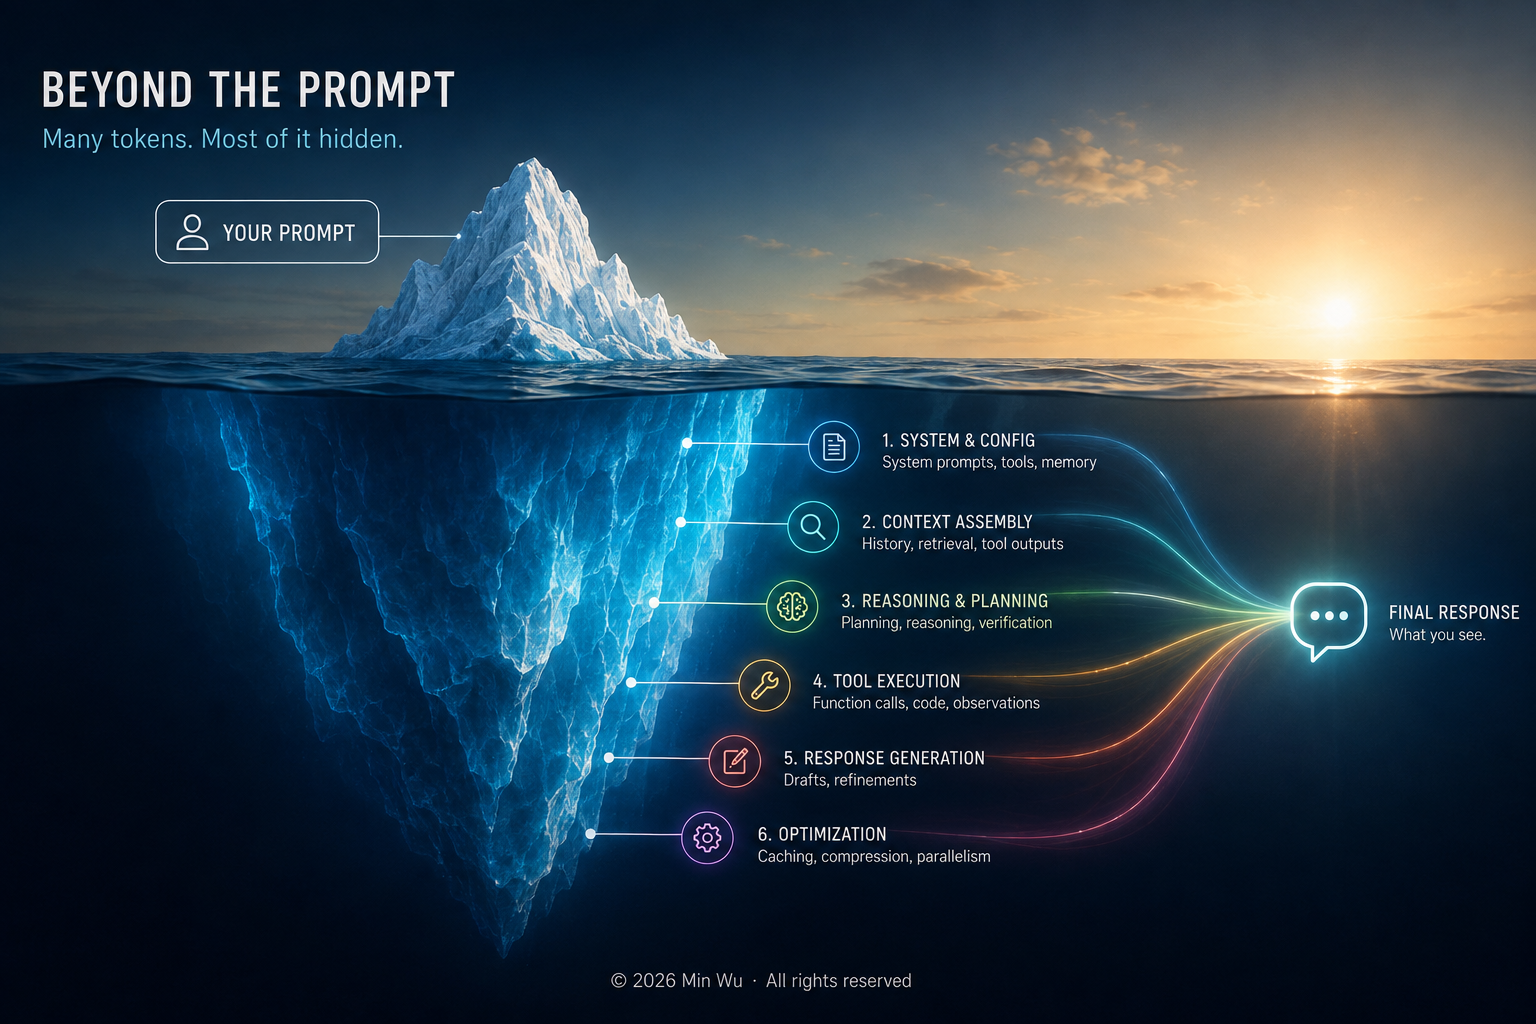
Today's LLMs provide cost accounting, not computational accountability. Input, output, and even reasoning tokens reveal how much compute was consumed, but reveal very little about whether that compute was spent efficiently.
Modern LLM APIs routinely report token usage. Enterprise teams estimate operational costs from tokens, benchmark models by cost per million tokens, and monitor inference budgets as closely as latency.
Yet one surprisingly fundamental question remains unanswered:
Where did all those tokens actually go?
For a traditional chatbot, the answer was relatively simple: the model read the prompt and generated a response. But modern agentic AI systems are fundamentally different. A single user request may trigger planning, retrieval, browser interaction, code execution, multiple tool calls, internal reasoning, self-verification, and re-planning before a final response is ever produced.
As a result, the visible prompt and final answer often represent only a small fraction of the total computational workload.
More importantly, while today’s APIs provide increasingly accurate token accounting, they provide remarkably little token attribution. We know how much compute was consumed—but not where it was spent, why it was needed, or whether it was used efficiently.
That transparency gap is becoming an increasingly important evaluation problem for agentic AI.
🤖 From Prompt-Response to Agentic Workflows
The mental model many people still have for LLM inference is remarkably simple:
User Prompt
      ↓
     LLM
      ↓
Final Response
In reality, modern AI agents operate much more like this:
User Request
      ↓
Context Construction
      ↓
Planning
      ↓
Tool Calls
      ↓
Document Retrieval
      ↓
Internal Reasoning
      ↓
Verification
      ↓
Re-planning
      ↓
Final Response
Each stage consumes tokens.
Many stages execute repeatedly.
Several stages are entirely invisible to users.
Suppose an API reports:
Input Tokens:      9,500
Output Tokens:       850
Reasoning Tokens:  4,200
Most people naturally assume those numbers correspond roughly to their prompt and response.
In reality, those 9,500 input tokens may include:
- System instructions
- Developer prompts
- Tool definitions
- Conversation history
- Retrieved documents (RAG)
- Browser observations
- Tool outputs
- Memory injection
The user’s actual prompt may represent only a few hundred tokens.
📊 A Taxonomy of Token Consumption
Thinking about token usage simply as Input Tokens + Output Tokens is no longer sufficient for agentic AI.
The workflow below summarizes where tokens may be consumed during a typical autonomous agent execution.
| Stage | Major Token Sources |
|---|---|
| Request Construction | System prompts, developer prompts, tool definitions, memory injection |
| User Inputs | User prompts, uploaded documents, images, audio |
| Context Assembly | Conversation history, RAG documents, tool outputs, browser state |
| Internal Agent Reasoning | Planning, reasoning, reflection, verification, re-planning |
| Tool Execution | Function arguments, function outputs, screenshots, code execution |
| Response Generation | Draft responses, final answer |
| Infrastructure Optimization | Prompt caching, context compression, parallel agent execution |
One observation immediately stands out.
Most token-consuming activities occur before the final response is ever generated.
🧠 The Three Types of “Reasoning”
Reasoning models have introduced another source of confusion: not all “reasoning” is the same.
There are really three different concepts:
| Type | Visible? | Typical Token Accounting |
|---|---|---|
| Internal reasoning | ❌ | Sometimes reported only as reasoning tokens |
| Reasoning summaries | ⚠️ Sometimes | Counted as normal output |
| Step-by-step explanations | ✅ | Counted as output tokens |
Suppose a reasoning model reports:
Input Tokens:        900
Reasoning Tokens:  4,800
Output Tokens:       300
A common misconception is that the model secretly wrote a hidden 4,800-token essay.
That is almost certainly not what happened.
Those reasoning tokens represent internal computation—exploring alternatives, checking intermediate results, revising plans, correcting mistakes, and verifying consistency before committing to a final answer.
The provider may report how many reasoning tokens were consumed, but generally does not reveal how those reasoning tokens were actually used.
Consequently, users know how much reasoning occurred, but not whether that reasoning was efficient.
👁️ The Token Transparency Gap
This leads to what I believe is an increasingly important concept:
The Token Transparency Gap
Today’s frontier APIs generally report only a handful of aggregate metrics:
- Input tokens
- Output tokens
- Cached input tokens (sometimes)
- Reasoning tokens (for selected models)
Those metrics are useful for billing and capacity planning.
They are much less useful for evaluating agent behavior.
Consider the following questions:
- How many tokens were spent on retrieval?
- How much context came from system prompts?
- Did the agent repeatedly retrieve the same documents?
- Did planning require multiple retries?
- Was verification responsible for most of the cost?
- Was the reasoning proportional to the task complexity?
Current APIs rarely answer any of them.
Instead, many different computational activities are collapsed into a few high-level counters.
In other words:
Today’s LLMs provide cost accounting—not computational accountability.
📏 Token Counts Are Not Efficiency Metrics
Suppose two frontier reasoning models solve exactly the same benchmark.
| Model | Reasoning Tokens | Accuracy |
|---|---|---|
| Model A | 800 | 95% |
| Model B | 8,000 | 95% |
Which model is better?
Today’s benchmarks generally cannot answer that question.
This highlights a metric that has received surprisingly little attention:
Reasoning Efficiency = Task Quality ÷ Reasoning Compute
Reasoning compute may include:
- reasoning tokens,
- inference latency,
- FLOPs,
- energy consumption,
- or combinations thereof.
As reasoning models become increasingly capable, achieving the same quality with significantly less computation will likely become a competitive advantage.
In other words, future model comparisons may increasingly resemble comparisons between algorithms—not just between answers.
🔍 The Missing Evaluation Dimension
One aspect of this discussion stands out from an evaluation perspective.
The majority of token-consuming activities are not directly observable.
| Category | Observable | API Reported | Auditable |
|---|---|---|---|
| User Prompt | ✅ | ✅ | ✅ |
| Uploaded Files | ✅ | ✅ | ✅ |
| Conversation History | ⚠️ Partial | Included in Input Tokens | ⚠️ Partial |
| Retrieved Documents | ⚠️ Partial | Included in Input Tokens | ⚠️ Partial |
| Tool Outputs | ⚠️ Partial | Included in Input Tokens | ✅ |
| Final Response | ✅ | ✅ | ✅ |
| System Prompt | ❌ | ❌ | ❌ |
| Developer Prompt | ❌ | ❌ | ❌ |
| Memory Injection | ❌ | ❌ | ❌ |
| Planning | ❌ | ❌ | ❌ |
| Internal Reasoning | ❌ | ⚠️ Sometimes | ❌ |
| Reflection & Verification | ❌ | ❌ | ❌ |
This means that independent evaluators often receive only a partial view of an agent’s computational behavior.
They can observe the final cost.
They rarely observe how that cost was generated.
🎯 Why This Matters
The AI industry has spent the past several years measuring capability.
Agentic AI is shifting attention toward computation.
Today, procurement teams increasingly compare:
- cost per million tokens,
- inference latency,
- benchmark accuracy,
- and reasoning token consumption.
Those metrics remain important—but they are incomplete.
As autonomous agents become longer-horizon, tool-using, and reasoning-intensive, another evaluation dimension is emerging:
Token transparency.
Future AI systems may need to report not only how many tokens were consumed, but also where those tokens were spent.
Imagine an API response that looked like this:
| Workflow Stage | Tokens |
|---|---|
| System & Tool Definitions | 6,200 |
| User Input & History | 4,800 |
| Retrieved Knowledge | 8,900 |
| Planning | 1,900 |
| Internal Reasoning | 11,300 |
| Verification | 3,100 |
| Tool Outputs | 4,200 |
| Final Response | 900 |
Such reporting would immediately reveal questions that are almost impossible to answer today:
- Is retrieval dominating the cost?
- Is the agent repeatedly re-planning?
- Is verification consuming excessive compute?
- Is reasoning proportional to task difficulty?
Most importantly, it would allow researchers and enterprise buyers to evaluate not only what an AI agent achieved, but also how efficiently it achieved it.
Token accounting helped us understand the cost of AI.
The next frontier may be computational accountability—understanding where that computation actually went.